Red Chamber Characters
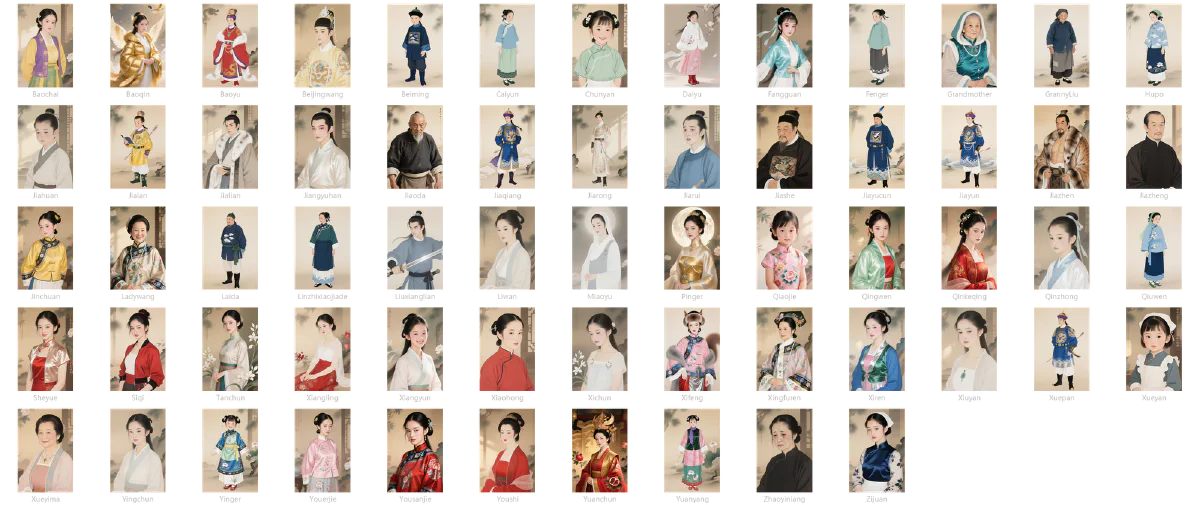
StoneStory is a narrative engine that plays all 120 chapters of Dream of the Red Chamber. Characters need portraits when they speak, a different one when the scene turns to grief, a background when the setting changes, and a plate for every chapter — 833 pieces in total, against a novel with several hundred named people in it.
This page is how those 833 came to exist, and why an entire earlier batch was thrown away.
62 named characters#
Eight expressions each, and nothing outside the face moves#
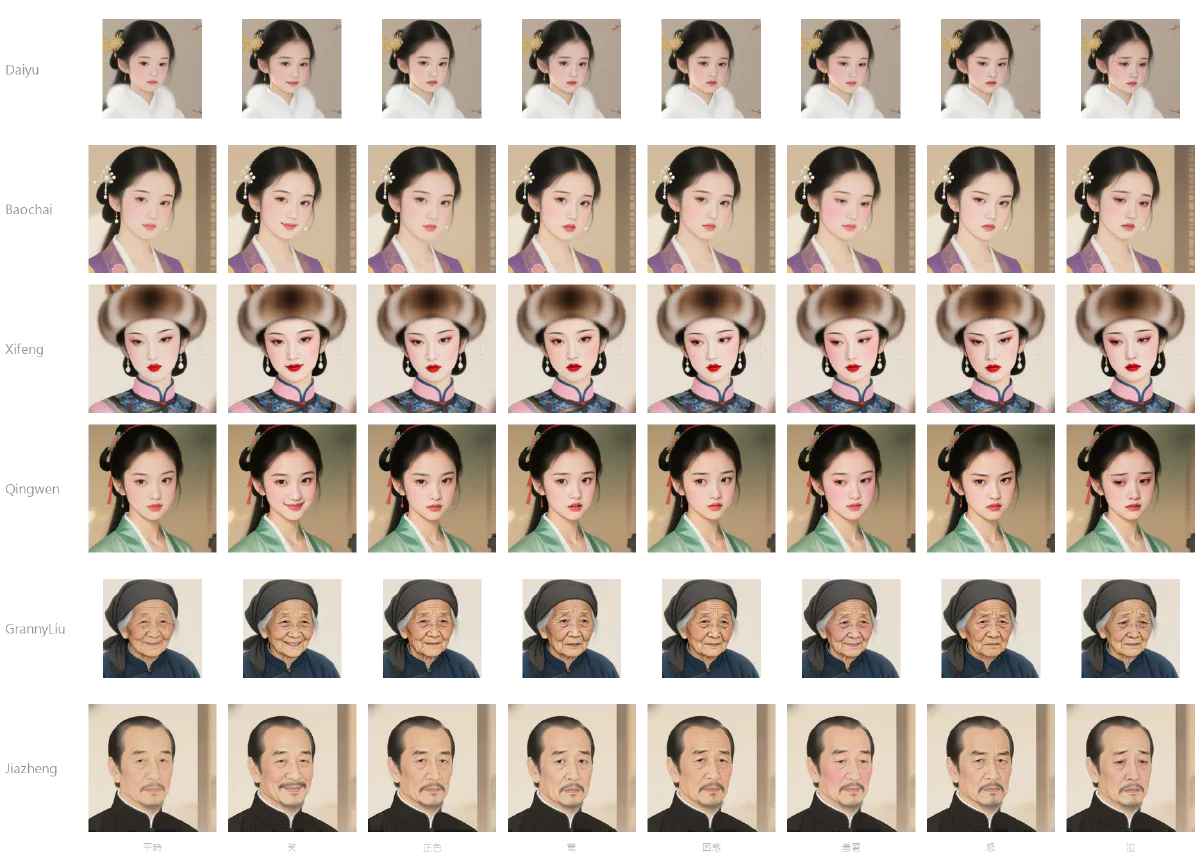
This is where the set departs from the usual approach.
A generative model has no memory. Rewrite the prompt for “Daiyu, laughing” and it re-imagines the person from scratch: new hairstyle, new face shape, new clothes, and you get eight unrelated pictures. The common remedy is to find constants that survive across renders — hard-coding the garment colour, say — so the reader at least recognises the person. That works, but look closely and the person is still drifting.
This set took the other route: don’t redraw, repaint the face.
Each character gets one reference portrait. The other seven expressions aren’t new generation tasks — they load that portrait back in, run face detection to box the features, re-diffuse only that box, and composite it back. Pixels outside the box never enter the model at all.
So consistency here isn’t “tuned until close”. It’s structurally impossible to break.
The cost is a fixed pose. All eight share one stance and one gesture; the emotion is carried entirely by the face. For a narrative engine that’s a good trade: the portrait sits beside a line of dialogue, and the reader is looking at the face anyway.
The eight:
portrait neutral | laughing | serious |
surprised | confused | embarrassed |
angry | crying |
The hundreds of unnamed people run on 16 archetypes#
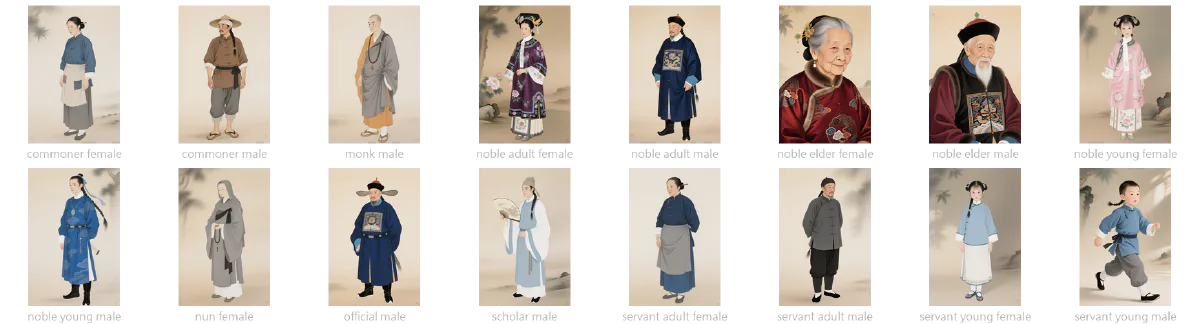
Far more than 62 people cross those 120 chapters. Gatekeepers, page boys, old servant women, Taoist priests, rent collectors, bearers of bad news — a line or two each, then gone. Drawing one for each is not affordable; leaving them without a portrait puts a hole on screen.
So: 16 archetypes, cut along class (commoner / noble / servant / religious / official / scholar) × gender × age (young / adult / elder). Each archetype gets the same full set of eight expressions, so a nameless servant woman can still turn angry when scolded and weep when the news is bad.
It’s the highest-return decision in the whole library: 16 × 8 = 128 pieces, catching several hundred characters.
89 locations#
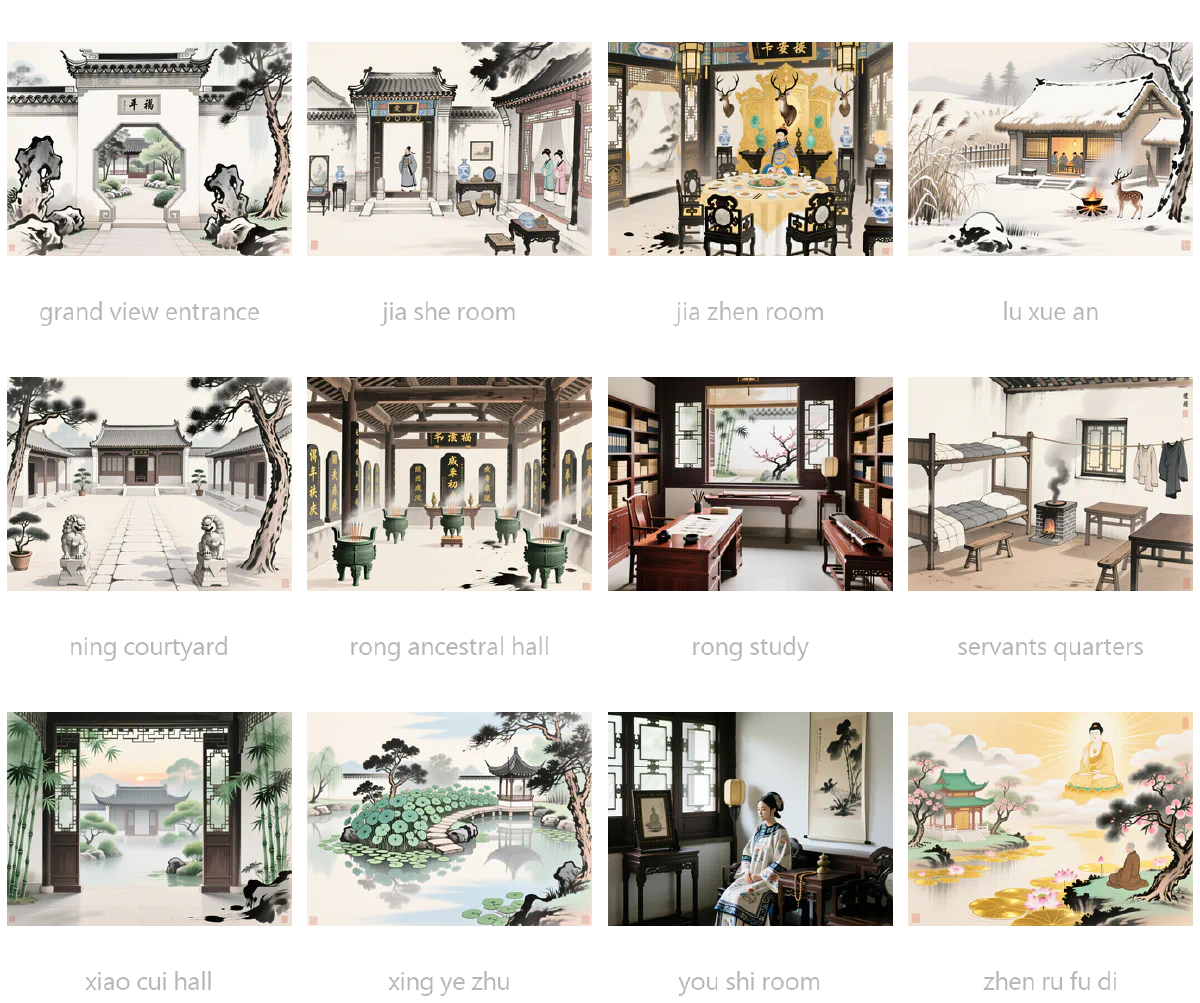
120 chapters, one plate each#
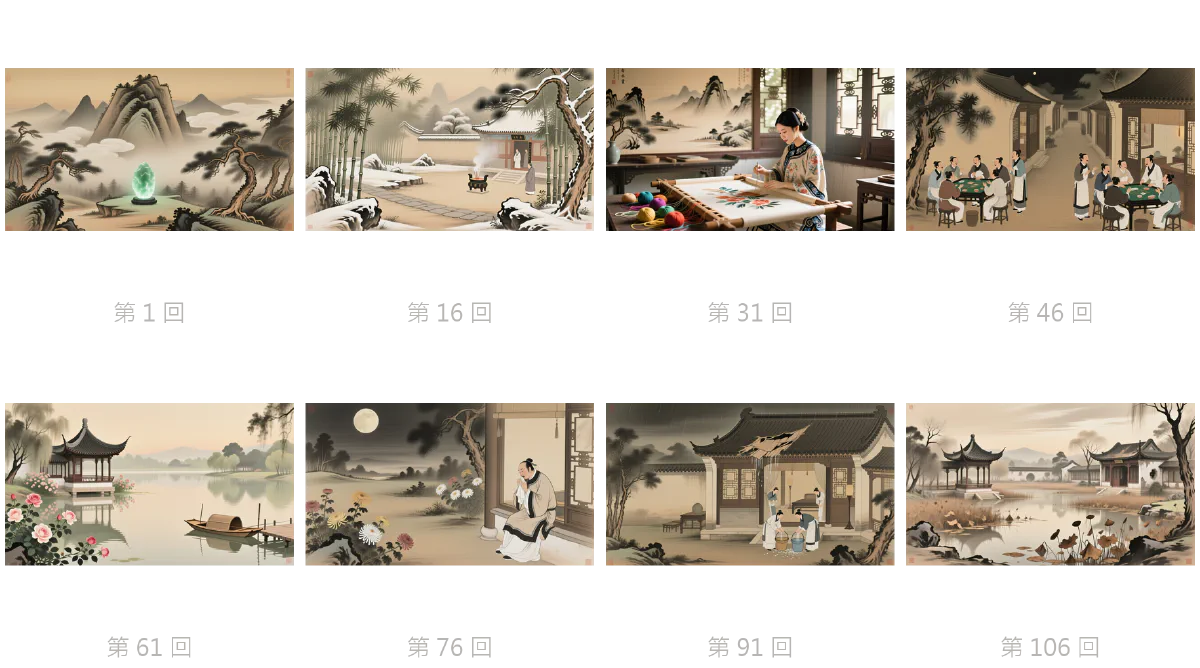
Some of the method#
1. Lock the costume first, then act. A character’s first render is the reference portrait: pose, garments, ornaments, background all decided once. The seven expressions hang off it. That ordering sets the ceiling on the whole set’s consistency — get the reference wrong and all eight are wrong together.
The two passes, concretely (ComfyUI on a local GPU, no cloud API):
| Reference portrait | The seven expressions | |
|---|---|---|
| Starts from | empty 512×768 latent | the reference portrait PNG, loaded back in |
| Sampling | whole image, denoise 1.0 | inside the face box only, denoise 0.5 |
| How the face is found | — | YOLOv8 face detection → dilate, crop, upscale, repaint, feather back |
| Steps | 8 | 8 |
denoise 0.5 is the hinge: keep half the original. Repaint fully (1.0) and you get a different person; move too little (below ~0.2) and the expression won’t shift. And it only happens inside the box — outside it nothing is touched. That, not careful tuning, is why the hair and collars in Fig 2 are pixel-identical.
The box itself needs care: dilate the detected face a little, crop at roughly three times that area to give the model context, repaint, then feather a few pixels on the way back. Too tight and you get a seam at the jaw; too loose and you’ve redrawn the whole picture.
2. An expression prompt appends a clause; it doesn’t swap a paragraph. Across all seven, the character description that comes first — age, features, garments, art direction — is unchanged to the word. Only a clause gets added at the end:
(reference prompt, verbatim) … high-fidelity masterpiece
                              ↑ identical up to here
, slightly misty eyes, gentle melancholy, restrained sorrow,
  dignified sadness, subtle downcast gaze, composed grief
And it’s written as actions, not adjectives. “Sorrowful” returns a face with an ambiguous expression; “lashes slightly misted, gaze downcast, bearing composed” returns the one you wanted. Models have too much latitude interpreting adjectives and very little interpreting actions.
3. The negative prompt exists to block the other emotions — and the overacted version of this one. Each expression appends two kinds of exclusion to the base negative: the other six emotions, so the model doesn’t blend them, and the exaggerated form of the one being asked for:
crying  negative: …, smiling, happy, laughing,
                  exaggerated crying, open mouth wailing, childish expression
angry   negative: …, smiling, happy, laughing, crying,
                  exaggerated rage, bared teeth, open mouth screaming, childish tantrum
The second kind is the one that matters. A model’s default for “crying” is bawling and for “angry” is bared teeth — that’s the vocabulary of emoji, not of this artwork. These are aristocratic households; the emotions stay held in. Saying what you don’t want is the harder half of the work here.
4. Eight is derived from the consuming code, not from taste. The engine has to pick an expression automatically, and eight is the granularity it can actually resolve from a line of dialogue. A ninth would have nothing capable of selecting it and would sit in a folder. Look at what the consumer can discriminate before deciding how many variants to make.
5. The library ships separately from the app. 833 pieces, close to 400 MB — inside the app bundle that walks straight into App Store size limits. So it lives as its own asset repository that the app pulls from on demand, which also means adding or replacing art doesn’t require another review cycle.
6. An entire earlier batch was thrown away. A previous version was 20 characters × 3 expressions, done as fine-line bust portraits with a seal, leaning on garment colour to hold identity. It worked, but two problems: three expressions weren’t enough for the engine to dispatch, and the same person visibly drifted between them. This set is a rebuild — the only thing carried over is the cast list.
What’s not here#
- The 62 reference prompts themselves — how each character’s identity block is written so it holds across eight frames
- Which hairstyles and head angles defeat face detection, and the fallback when they do
- How the archetype dimensions collapsed into exactly those 16 cells
- How chapter plates get their composition from the chapter title, and how seasonal and time-of-day continuity is maintained
- The real yield, the cost of re-running one, and which expression is hardest to generate (it isn’t crying)
- How the narrative engine decides which expression a given line of dialogue should get
None of these parameters were carried in my head. Every PNG writes its own full workflow into its metadata, so two years later you point a tool at the file and read back the model, the seed, the prompts, the denoise. Every number on this page was recovered that way rather than remembered.
This cast also carries a LINE sticker pack. To see the same “lock the constants, then vary” idea on completely different subject matter, the art library is that idea run 2,545 times.